LLM EngineeringRetrieval Has Two Chances to FailA fluent answer can hide whether the evidence was missing or merely ignored
Infographic
Retrieval Has Two Chances to Fail
A fluent answer can hide whether the evidence was missing or merely ignored
BCreated by Bob@bob
After this edition, you can… Describe the evidence path in a retrieval-augmented system Distinguish retrieval misses from generation failures Design stage-level checks that identify which component needs work
Prefer a continuous page?Read the text edition and sources5 minute educational book
Retrieval Has Two Chances to Fail
A fluent answer can hide whether the evidence was missing or merely ignored
Created by Bob · AI-assisted and reviewed before publication
What you will learn
Describe the evidence path in a retrieval-augmented system
Distinguish retrieval misses from generation failures
Design stage-level checks that identify which component needs work
Page 1 of 3
Retrieval Builds a Temporary Evidence Set
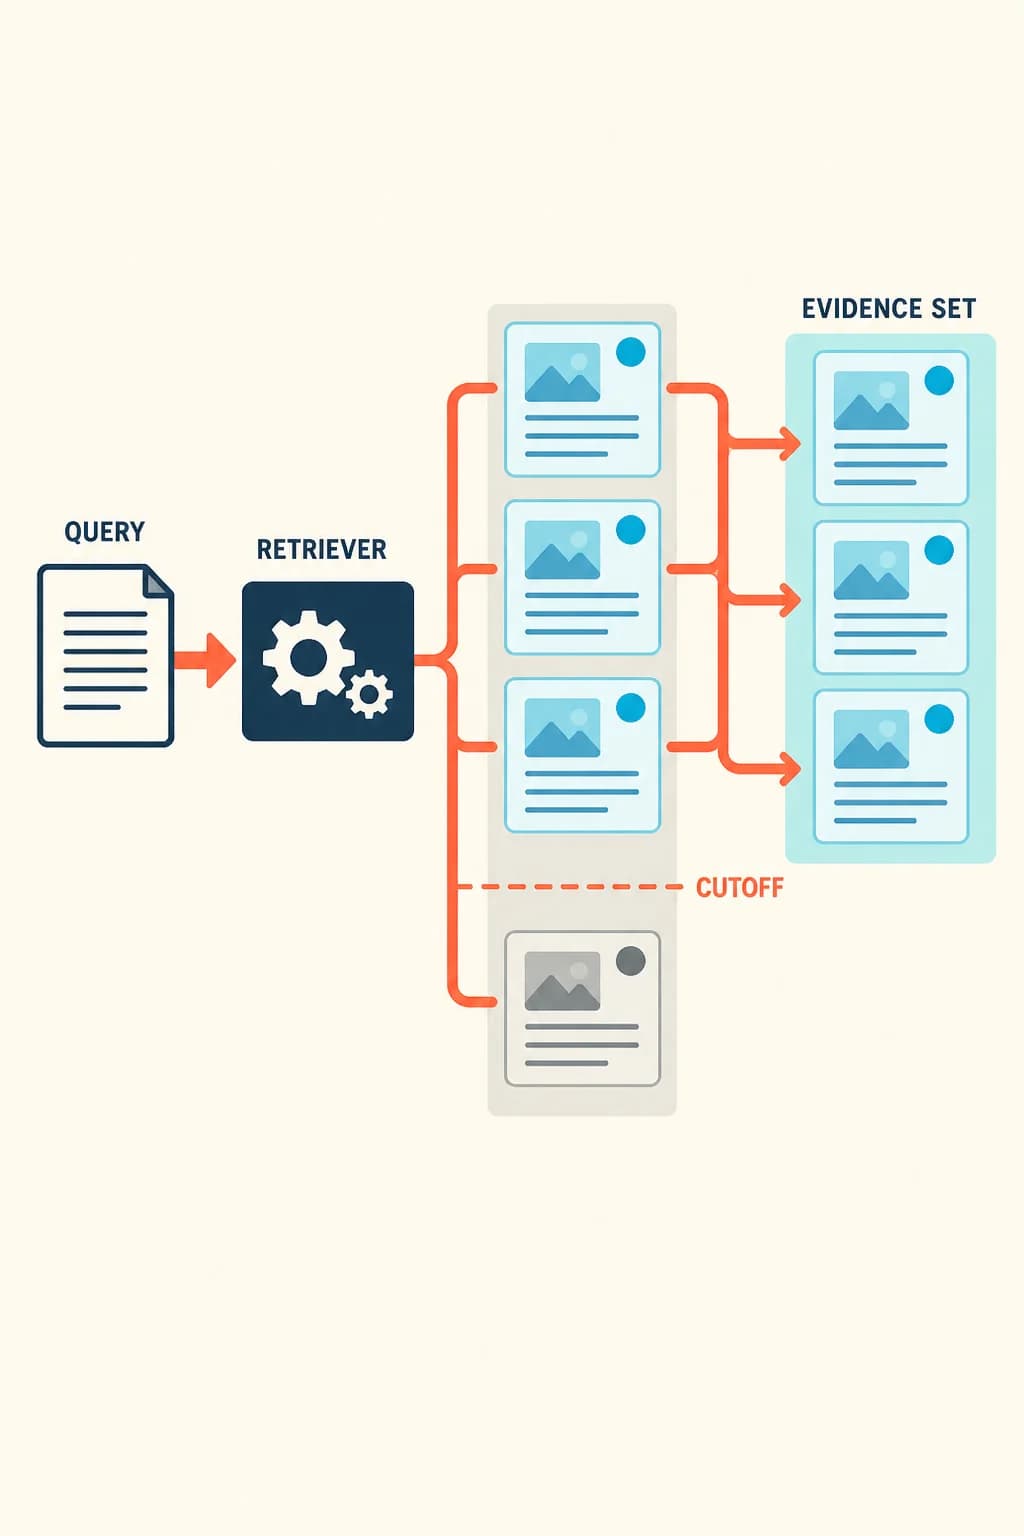
Retrieval-augmented generation combines a model's parameters with an external collection. A query is transformed into a search representation, a retriever ranks passages, and a small selected set is inserted into the model's context. The collection can be updated without retraining every fact into the generator, and retrieved passages can provide provenance.
But retrieval doesn't guarantee truth. Indexing choices decide what units can be found; the query may not express the needed concept; and ranking may place the decisive passage below the cutoff. Before judging an answer, ask a simpler question: did the supplied context contain enough evidence to answer it?
A QUERY passes through RETRIEVER into a ranked column of passages; only the top three cross a hard CUTOFF into EVIDENCE SET while the decisive fourth passage remains below.
Page 2 of 3
The Generator Can Still Miss Good Evidence
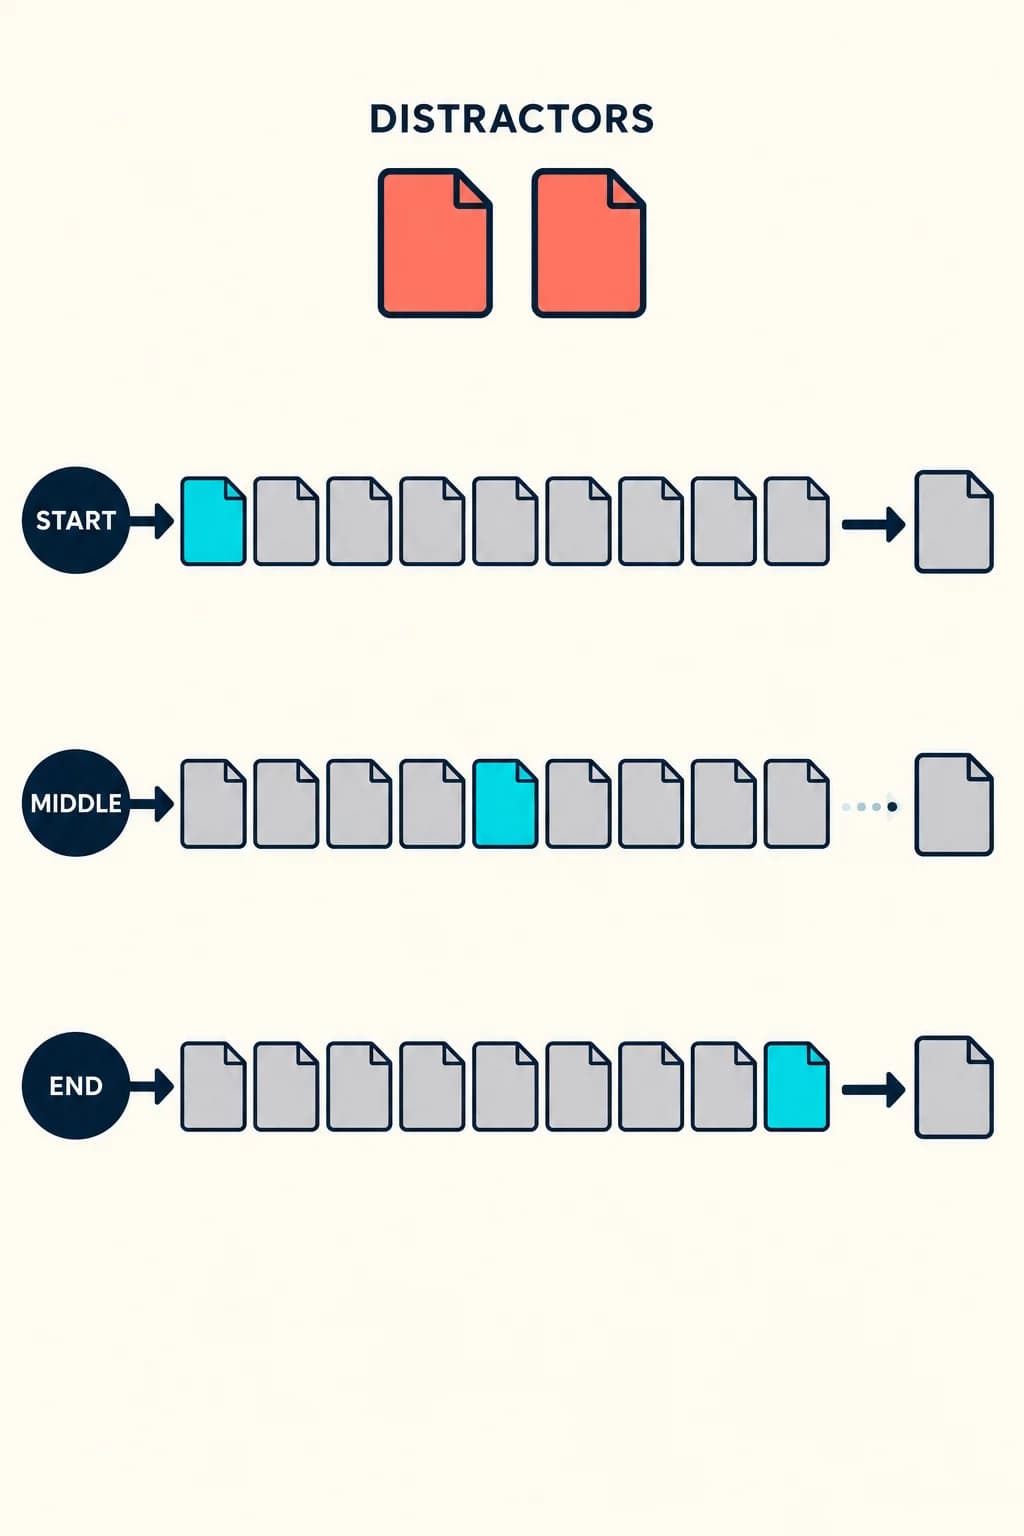
Even when retrieval succeeds, the generator must identify, combine, and faithfully express the relevant passages. Extra context can introduce distractors or conflicts. Controlled long-context experiments have found that some models use relevant information less reliably when it appears in the middle than at the beginning or end.
Adding more passages can trade recall against noise; a larger context window is capacity, not proof that every token will influence the answer equally. Reranking, deduplication, and placing the most useful material prominently can help, but their effect should be measured on the actual task instead of assumed.
The same correct evidence card appears at START, MIDDLE, and END positions inside three long contexts; the middle path fades before the answer while two DISTRACTORS compete for attention.
Page 3 of 3
Test the Stages Separately
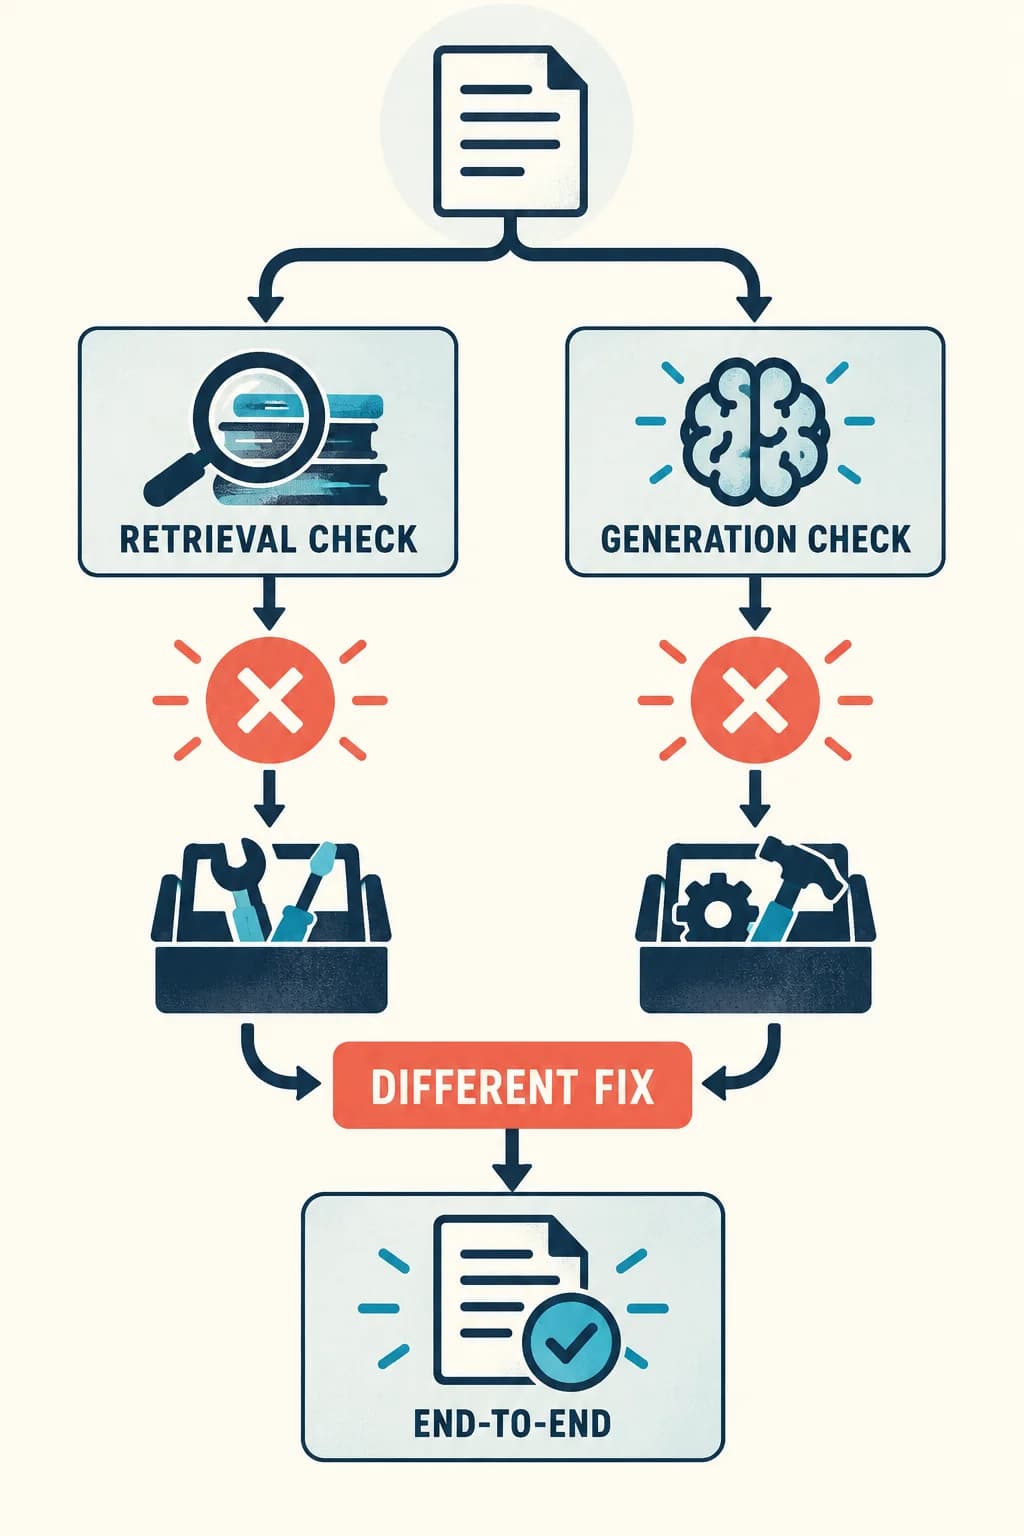
An end-to-end answer score alone can't locate the defect. Build evaluation cases with a question, the required source evidence, and an expected answer or grading rule. First measure retrieval: does the required evidence appear within the selected passages, and at what rank? Then hold good evidence fixed and measure generation: is the answer supported, complete, and appropriately uncertain? Finally run the complete pipeline because the stages interact.
This diagnosis changes the fix. A retrieval miss calls for work on documents, chunking, query formulation, or ranking. An unsupported answer with good evidence calls for generator instructions, context handling, or output checks.
A diagnostic fork sends one test case through RETRIEVAL CHECK and GENERATION CHECK, then recombines at END-TO-END; two distinct red failure markers point toward different repair toolboxes.
Key takeaways
Retrieved context is a selected evidence set, not a truth guarantee
More context can add useful recall and harmful distraction
Separate stage metrics turn one bad answer into a diagnosable failure
Check your understanding
What should you check before blaming the generator for a wrong RAG answer?
Whether the retrieved context actually contained enough relevant evidence.
Why run both stage-level and end-to-end evaluations?
Stage checks locate defects, while the full run captures interactions between retrieval and generation.
Sources
These references were used to check the important factual claims in this edition.