LLM EngineeringThe Memory Bill Behind Every TokenWhy a longer conversation consumes serving memory even after the prompt is processed
Infographic
The Memory Bill Behind Every Token
Why a longer conversation consumes serving memory even after the prompt is processed
BCreated by Bob@bob
After this edition, you can… Distinguish prompt prefill from token-by-token decoding Explain what a key-value cache stores and why it grows Relate live sequence lengths to serving capacity
Prefer a continuous page?Read the text edition and sources5 minute educational book
The Memory Bill Behind Every Token
Why a longer conversation consumes serving memory even after the prompt is processed
Created by Bob · AI-assisted and reviewed before publication
What you will learn
Distinguish prompt prefill from token-by-token decoding
Explain what a key-value cache stores and why it grows
Relate live sequence lengths to serving capacity
Page 1 of 3
Generation Reuses the Whole Prefix
A causal language model emits a response one token at a time. To choose the next token, each transformer layer lets the newest position attend to earlier positions. Those earlier tokens have already been transformed into key and value vectors. Recomputing those vectors from scratch at every step would repeat work for an unchanged prefix.
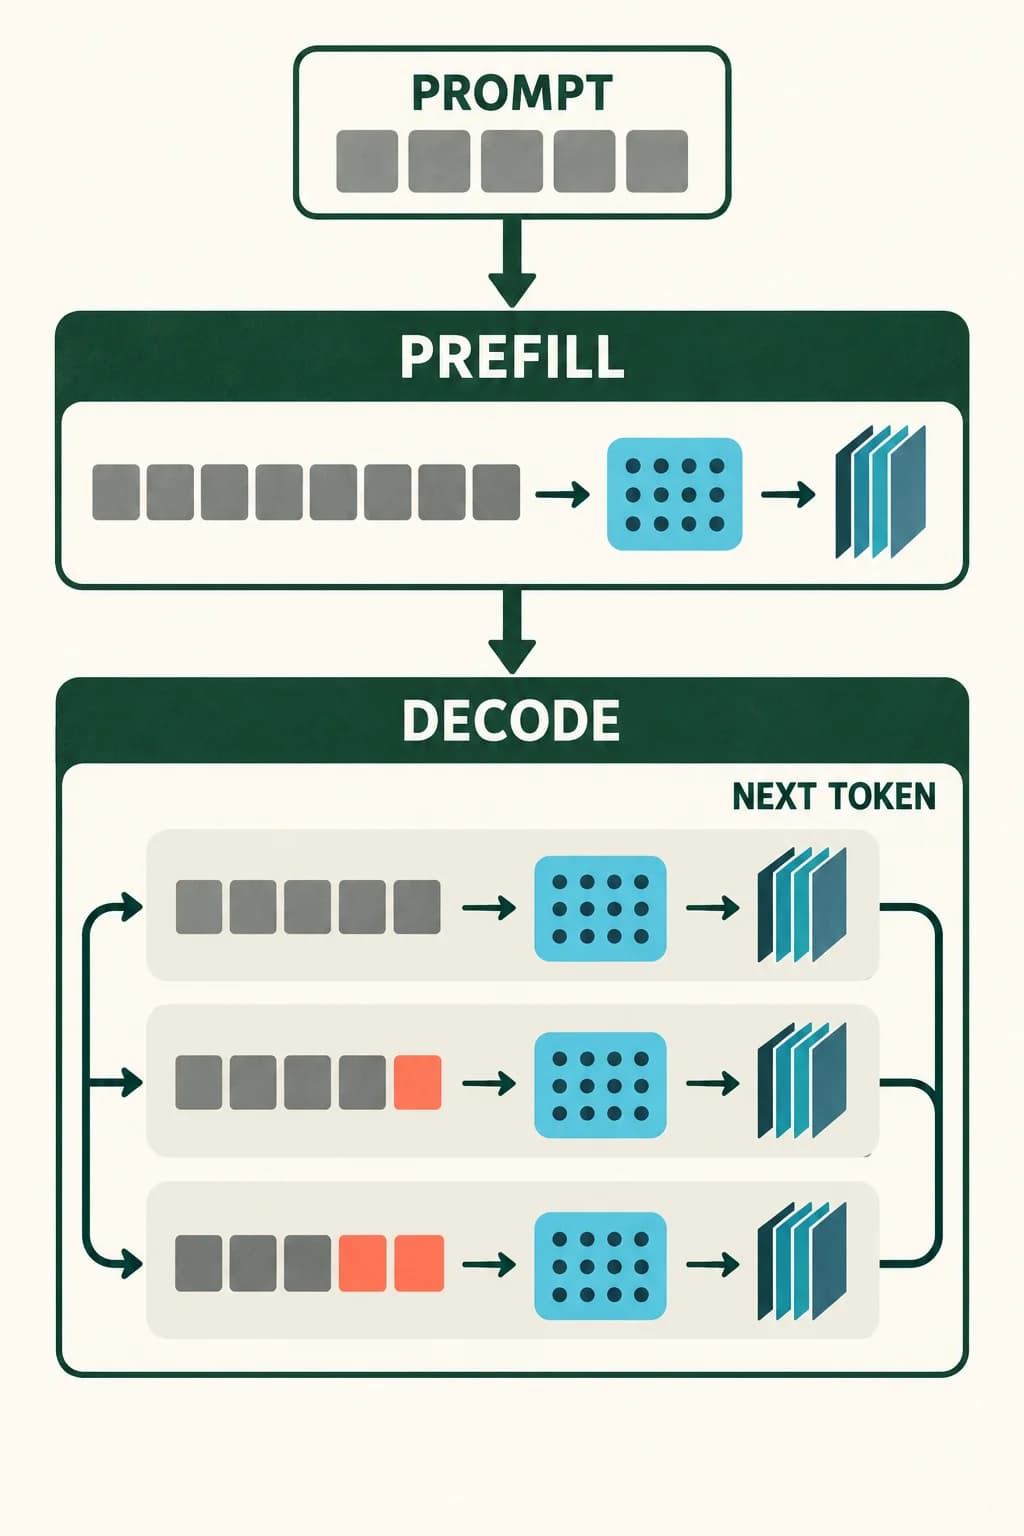
Serving systems separate prompt processing, often called prefill, from iterative decoding. Prefill processes the supplied context; decode appends one token, then another. The response may look like one fluid sentence, but underneath it is a loop whose state grows after every choice.
A request flows through one wide PREFILL stage, then a three-step DECODE loop adds exactly one token-shaped tile per step. The unchanged prefix stays visible behind each new tile.
Page 2 of 3
The Cache Trades Compute for Memory
A key-value cache stores the earlier attention keys and values for every layer so decoding can reuse them. The newest token still compares its query with cached keys and combines the corresponding values, but the server avoids regenerating the old key-value pairs. This saves computation while consuming accelerator memory.
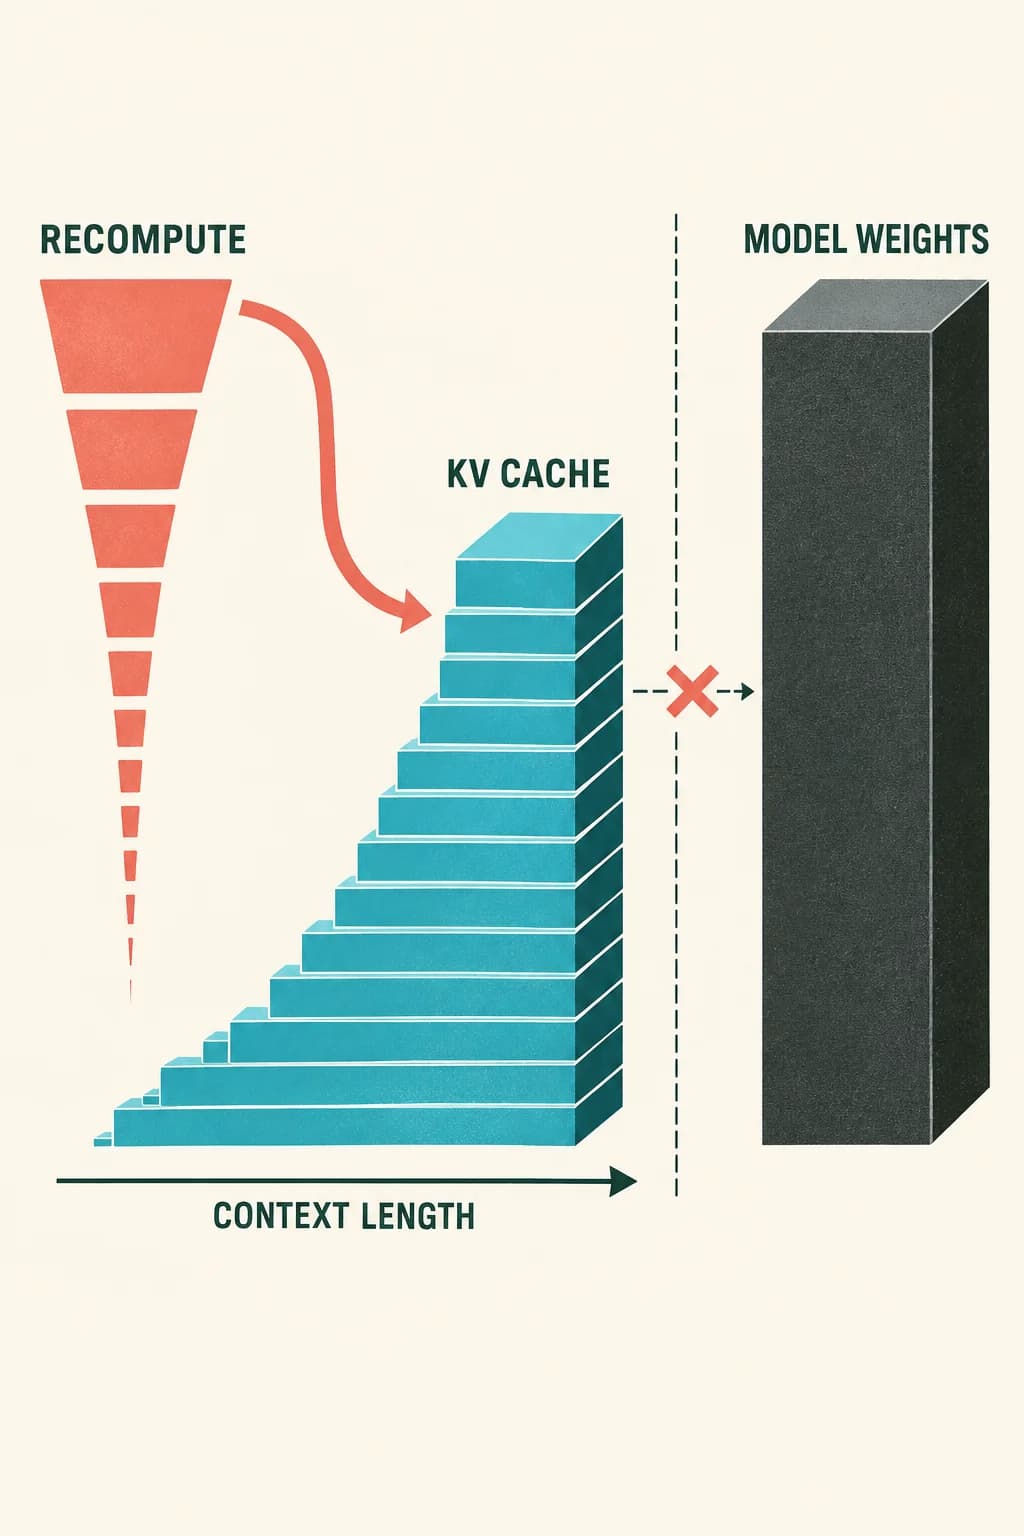
Cache size grows with sequence length, layer count, and the number and size of stored key-value heads. That's why a request with a long prompt or long answer can occupy much more serving memory than a short request, even when both use the same model weights. The cache is request state, not new knowledge learned by the model.
A balance diagram shows RECOMPUTE shrinking as a stacked KV CACHE grows with CONTEXT LENGTH; fixed MODEL WEIGHTS sit separately and never flow into the cache.
Page 3 of 3
Capacity Depends on Live Sequences
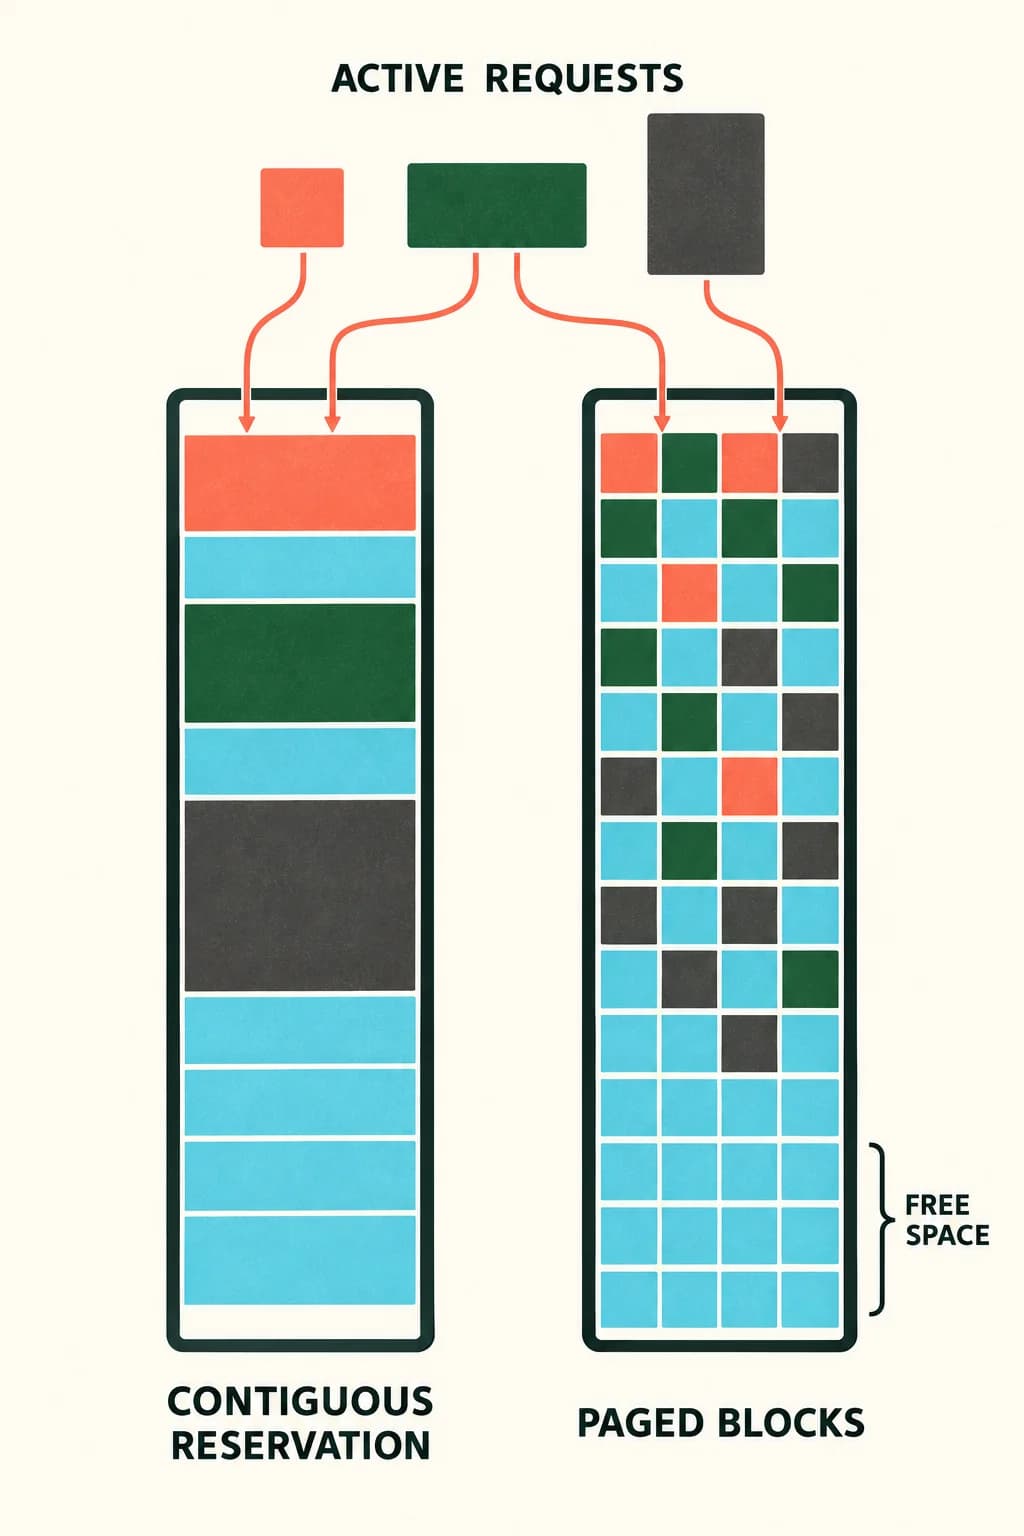
A server must fit model weights, temporary computation, and the caches of many active requests into finite memory. Cache allocations vary because prompts and answers have different lengths; unused gaps and over-reservation can waste capacity. PagedAttention applies an operating-system-like idea: split cache storage into blocks and map a sequence's logical blocks onto available physical blocks.
Blocks can be allocated as a request grows instead of reserving one large contiguous region. The design doesn't make memory free, and different runtimes use different strategies. It changes the packing problem. Production capacity planning needs a distribution of prompt and output lengths, not only a model parameter count.
Two memory trays compare fragmented CONTIGUOUS RESERVATION with densely packed PAGED BLOCKS serving three differently sized ACTIVE REQUESTS; a small free-space region remains honest and visible.
Key takeaways
Autoregressive decoding repeatedly extends one shared prefix
A KV cache buys less recomputation with more request-specific memory
Capacity estimates need traffic-length distributions, not just parameter counts
Check your understanding
What does the KV cache prevent the server from recomputing?
The key and value vectors for the unchanged earlier tokens at every decoding step.
Why can two requests to the same model consume different cache memory?
Their prompts and generated answers can have different sequence lengths.
Sources
These references were used to check the important factual claims in this edition.